MisGraphBenchmark
Does a larger token budget help?
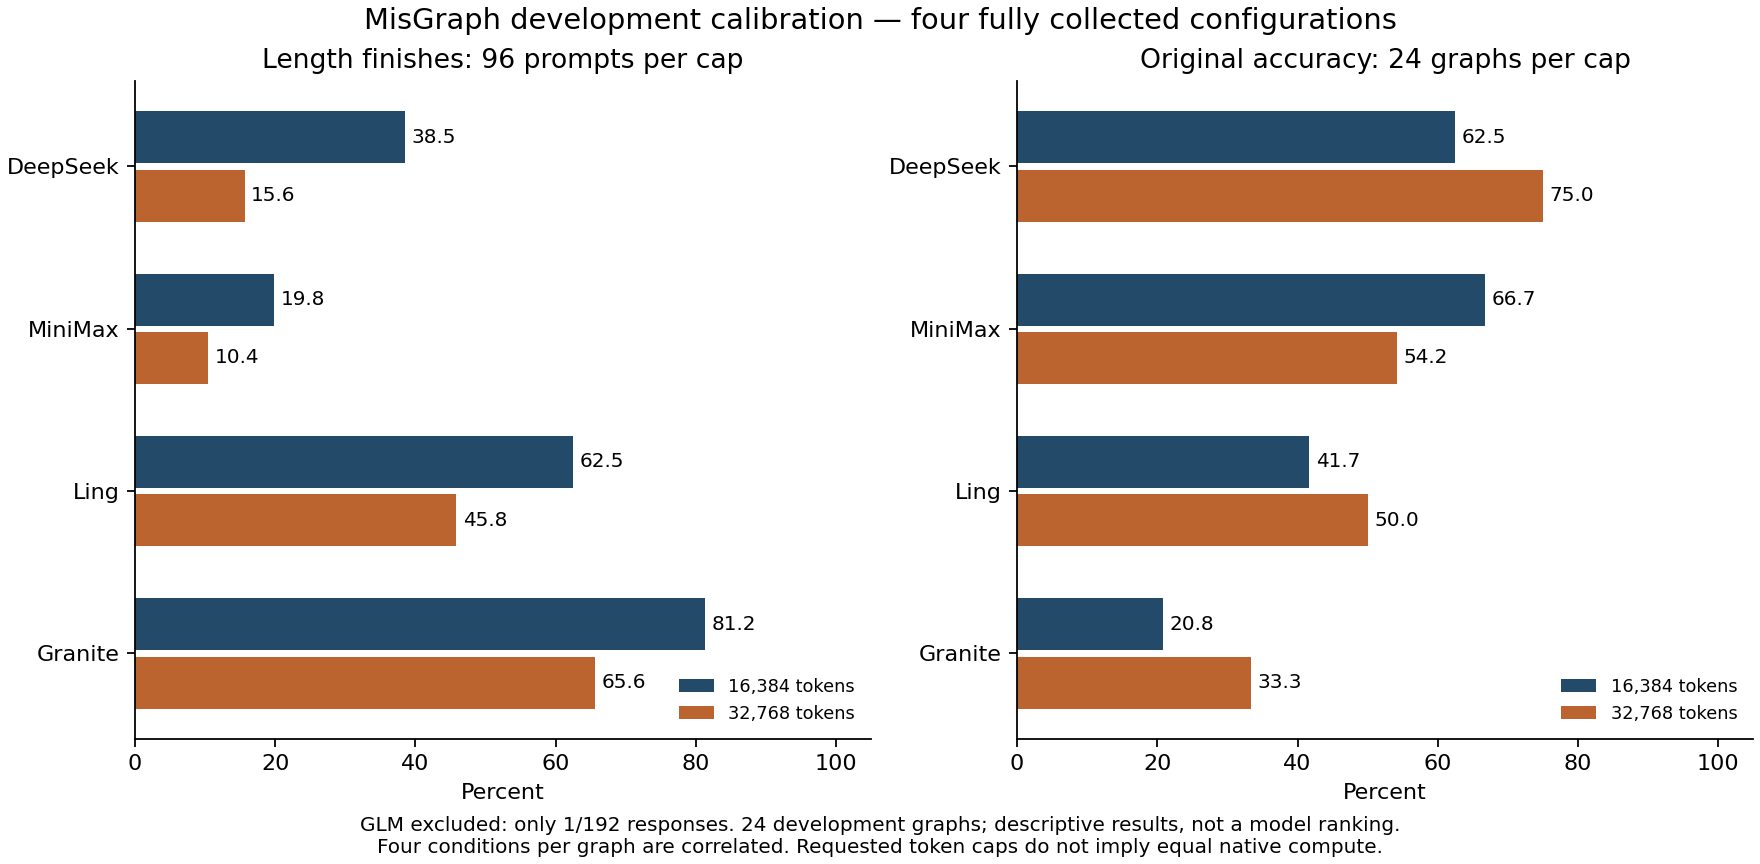
With twice the token allowance, all four configurations hit the limit less often. Three became more accurate; MiniMax became less accurate.
24 development graphs · four naming conditions · separate from the Hard v1 leaderboard
What changed at 32K?
| Configuration | Accuracy 16K | Accuracy 32K | Hit token limit 16K | Hit token limit 32K | Responses |
|---|---|---|---|---|---|
| DeepSeeksail-research/fp4 | 62.5% | 75.0% | 38.5% | 15.6% | 192 / 192 |
| MiniMaxtenstorrent/fp8 | 66.7% | 54.2% | 19.8% | 10.4% | 192 / 192 |
| Lingnovita | 41.7% | 50.0% | 62.5% | 45.8% | 192 / 192 |
| Granitecoreweave/bf16 | 20.8% | 33.3% | 81.2% | 65.6% | 192 / 192 |
GLM: 1/192 responses. Its 32K setup requests failed after all approved retries, so we cannot compare the two token limits for GLM.
Study details and downloads
We tested the same 24 graphs at limits of 16,384 and 32,768 completion tokens, using original, repeated, neutral and degree-reversed prompts. Each model kept the same provider and settings. Wrong, invalid and truncated answers were kept without retries.
Accuracy counts invalid and truncated responses as well as completed answers. “Hit token limit” counts every response that reached the limit, even if it gave the correct answer. The leaderboard’s cutoff column counts only those without a correct answer.
Each graph contributes four related prompts, so this is a small development sample. Hard v1 still uses its original 16K limit. A shared token cap does not give every model equal compute. The download includes confidence intervals and question-by-question changes in accuracy, agreement and cutoffs.
We collected 769 of 960 planned responses in 803 attempts. Providers reported $2.06198 in charges; allowing another $0.12876 for unconfirmed charges brings the total to $2.19074. All 24 answer certificates and fixed-file hashes passed verification.